
efaimo
io.github.efaimo-ai/efaimo
Read-only tools that grade an Agent Skill and measure its context-window token cost
Documentation


efaimo audits everything your agent loads: MCP servers and Agent Skills.
One CLI lints them, weighs their context cost, diffs servers against the 2026-07-28 spec,
and A/B-tests whether a skill actually helps.
Everything you plug into an agent spends two budgets before any work happens: context-window tokens, and the trigger quality that decides whether the right tool fires at all. Good tools exist for single slices of that problem; efaimo's job is the whole audit in one command, for both halves of what an agent loads. Lint a skill, weigh a server's tool definitions, get a migration diff for the 2026-07-28 stateless MCP spec, and measure whether a skill actually improves task completion (SkillsBench found curated skills made agents worse on 16 of 84 tasks; linting alone cannot catch that).
Agent Skills
npx efaimo check --skill ./skills/
Point it at one skill or a whole folder. It validates each skill against the agentskills.io spec and grades it:
check skill  claude-api
grade C (73)   1 error  2 warnings  4 info

  x S101  description is 1068 chars (spec max 1024)
  ! S104  instructions are ~18.4k tokens (spec recommends staying under 5k)
          fix: move detail into references/ files loaded on demand (progressive disclosure)
  ! S104  SKILL.md is 570 lines (spec recommends under 500)
  i S104  metadata level is ~294 tokens; the spec targets ~100 and this loads at
          startup for every installed skill
(That is Anthropic's own claude-api skill.) efaimo checks frontmatter and
trigger quality, collisions across an installed set, the context budget (metadata
loaded every session, body loaded on trigger), reference integrity, and injection
hygiene. Run it on a folder and every skill gets its own grade, not one aggregate.
We graded 36 public Agent Skills: every skill in anthropics/skills,
anthropics/claude-cookbooks, and obra/superpowers, at pinned commits. 97%
score an A, but even this curated set has real issues: Anthropic's own
claude-api scores a C (73) with an over-limit description and ~18k-token
instructions, and the median skill's instructions run ~1,632 tokens loaded on
every trigger. Full report, the corpus manifest, and the two commands that
reproduce it: the Skills Quality Index.
That index is a photograph. Measured twice re-runs the same corpus seven weeks later with the same ruleset: the cost that sits in context permanently moved -0.8%, the body +7.0%, and referenced files, which load out of sight and which no rule here counts, +61.4%. Grades moved one way only, 0 improved against 4 worse. The uncomfortable part points inward: the two columns this tool has thresholds for are the two that held.
Does the skill actually help? (experimental)
Linting tells you a skill is well-formed. It does not tell you the skill makes the
agent better, and research shows some skills make it worse. efaimo test measures
that directly: it runs a task with and without the skill, N trials each, and an LLM
judge scores every attempt.
npx efaimo test scenario.yaml                 # dry run: validate + show the plan, no API calls
npx efaimo test scenario.yaml --live          # run it for real (Claude or GPT)
npx efaimo test scenario.yaml --live --model gpt-4o-mini
Works with Claude (ANTHROPIC_API_KEY) or GPT (OPENAI_API_KEY) models; the
provider is picked from the model name. Put the key in your shell or a local
.env file (copy .env.example); a real shell variable always wins.
Two real runs (claude-sonnet-5, 8 trials each) show why this matters: a generic csv-cleanup skill that a capable model does not need, and a skill that encodes a convention the model cannot guess.
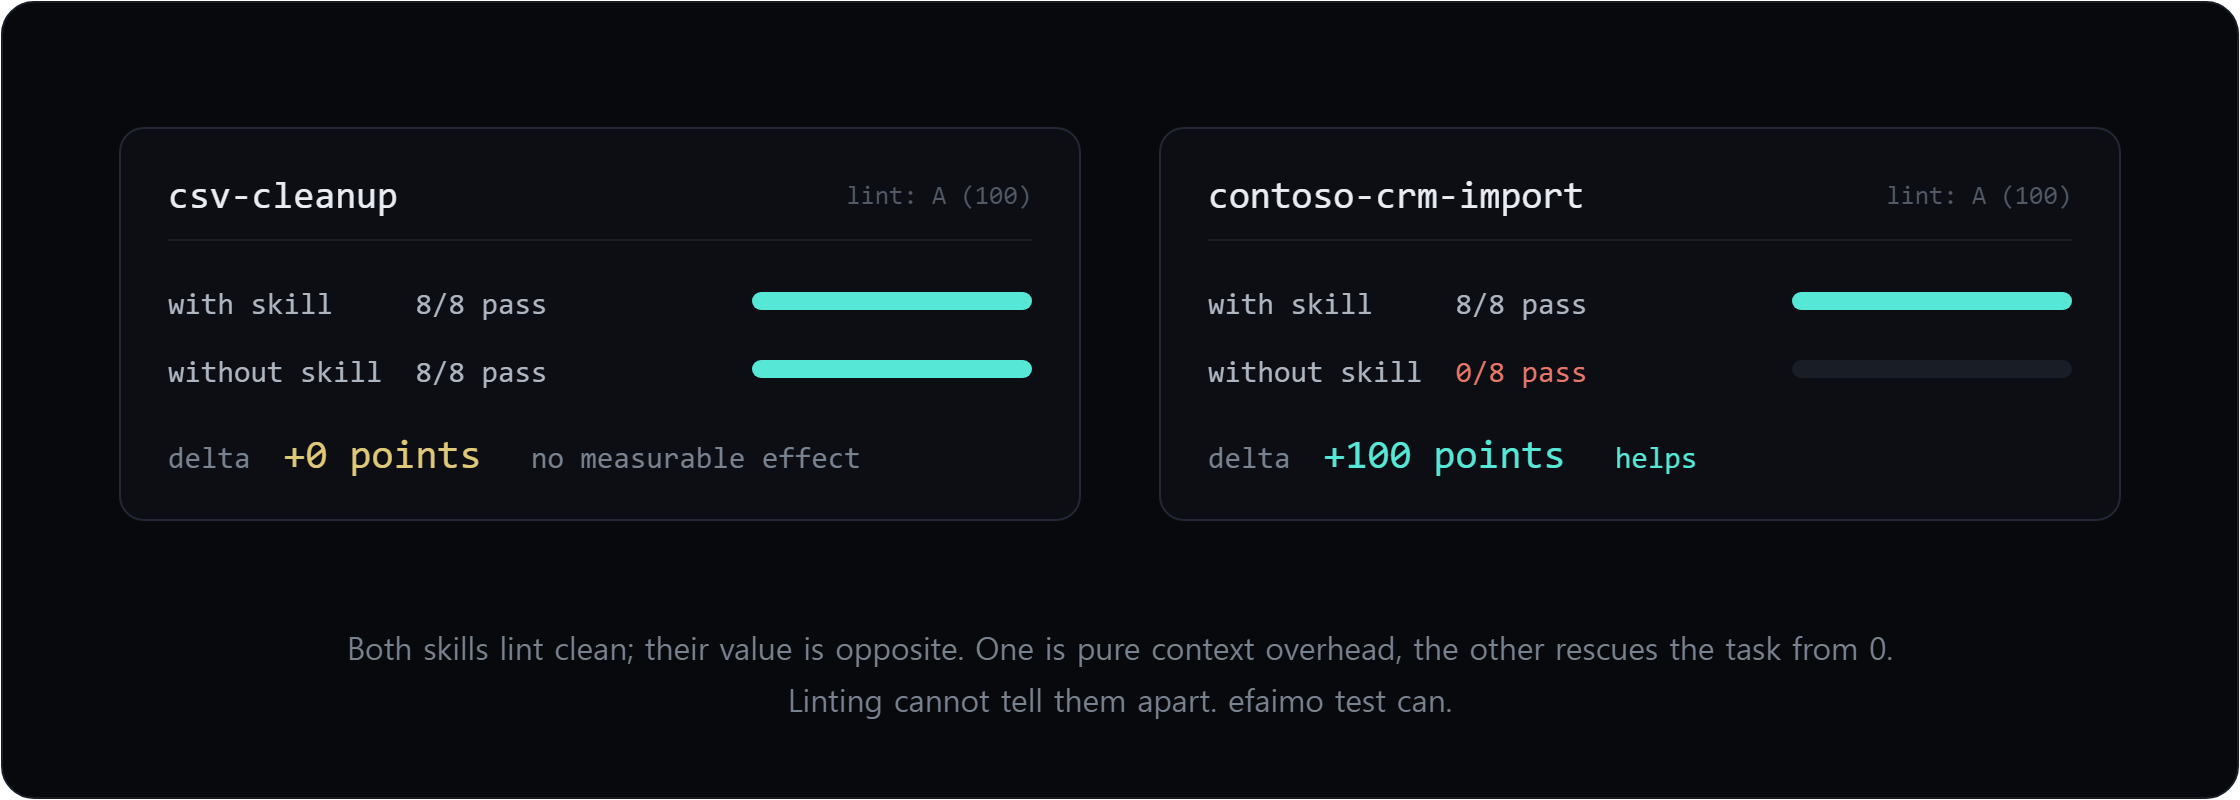
The two runs as copyable text
test  csv-cleanup helps on a messy CSV
  with skill     8/8 pass  (100%)
  without skill  8/8 pass  (100%)
  delta          +0 points   no measurable effect
test  contoso-crm-import helps on an unknowable format
  with skill     8/8 pass  (100%)
  without skill  0/8 pass  (0%)
  delta          +100 points   helps
The first is pure context overhead, the second earns its tokens, and only the trial data tells them apart.
The verdict is a significance test, not a threshold on the gap. Every run
reports a two-sided Fisher exact p and a 95% interval on the delta, and
helps / hurts require p < 0.05; anything else is no measurable effect
no matter how large the gap looks. That matters more than it sounds: at the
old default of 5 trials per arm, 5/5 against 4/5 is +20 points and a p of
exactly 1.0000, and the previous rule called it helps. The +100 run above
is p = 0.0002; a +25 run at 8 trials per arm is p = 0.47 and now says so.
The default is 20 trials per arm, because below about that a partial result
cannot reach significance at all.
It is opt-in because a live run spends tokens on your key. See examples/scenario.example.yaml and examples/scenario.crm.yaml.
MCP servers
npx efaimo weigh "npx -y my-mcp-server"      # what does it cost my context window?
npx efaimo check --mcp "npx -y my-server"    # quality grade + 2026-07-28 migration diff
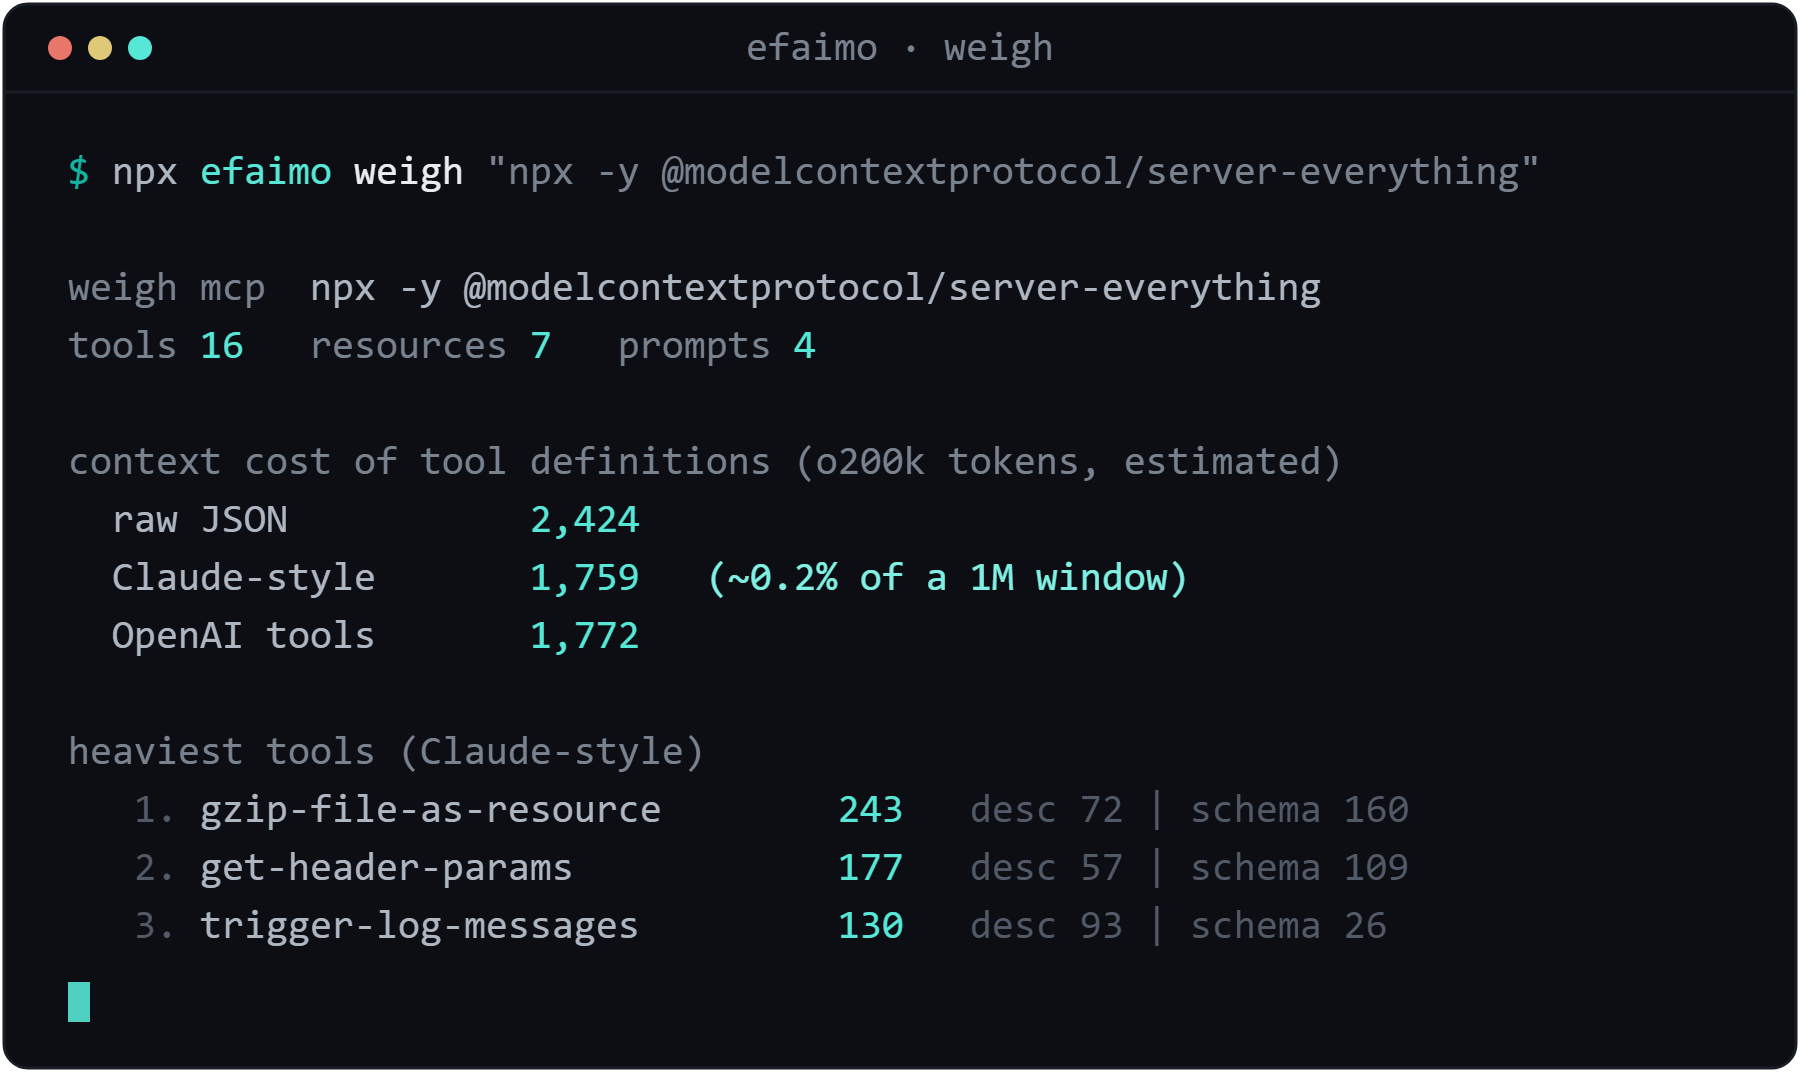
weigh reports the token cost of tool definitions in three real serializations,
per tool, with an optional --anthropic exact Claude count.
check --mcp connects live (it speaks both the legacy handshake and the new
stateless protocol, so a 2026-07-28 server audits fine) and reports two things,
separately. First, a quality grade for what models actually experience:
descriptions, schemas, annotations, tool count, token cost. Second, an ungraded
migration diff for the 2026-07-28 stateless spec (which removes
initialize and sessions, deprecates Sampling, Roots, and Logging, and requires
server/discover, resultType, and cache fields): exactly what will break and
how to fix it, each rule naming the SEP it came from. Readiness never drags the
grade, because the two answer different questions: the grade is what a model
experiences from this tool surface, readiness is whether a 2026-07-28 client can
talk to this server. Combining them scored the reference server a C for a tool
surface that is an A. Pass --strict-readiness when you want CI to fail on
the diff. Full list: docs/RULES.md.
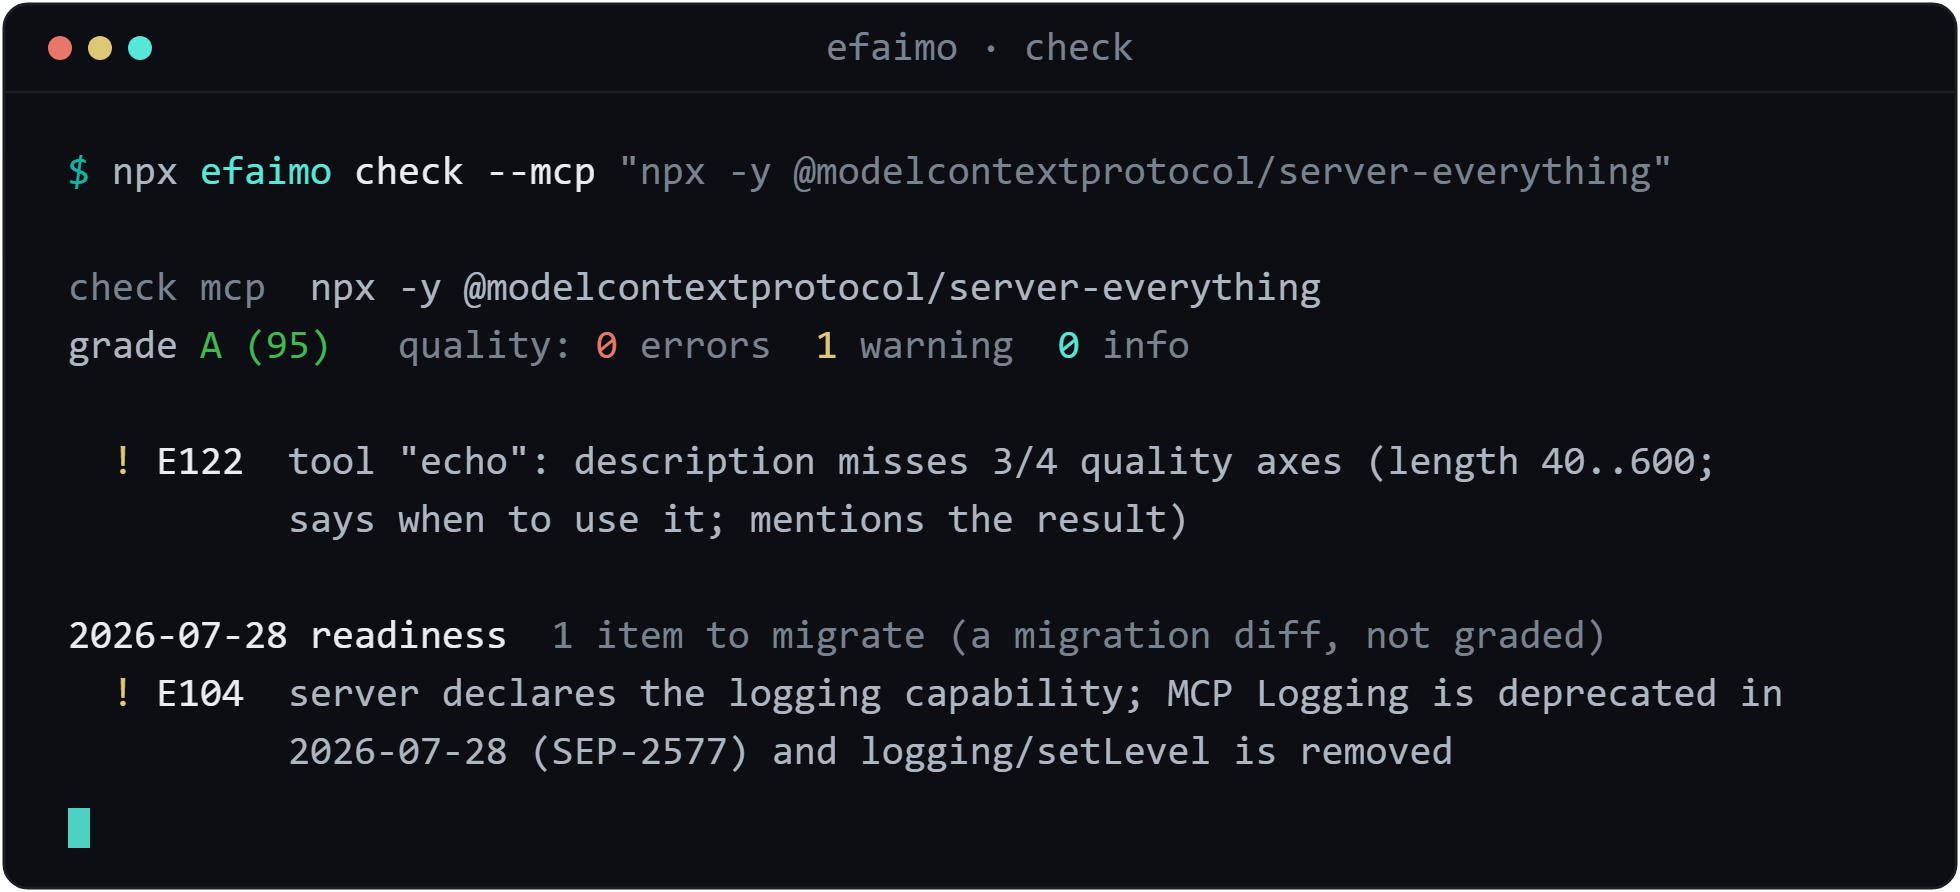
(That is the official reference server: solid quality, one thing left to
migrate. It had four until it moved to the 2.x SDK, which answers
server/discover and fills in the cache and resultType fields for you.)
The same output as copyable text
check mcp  npx -y @modelcontextprotocol/server-everything
grade A (95)   quality: 0 errors  1 warning  0 info

  ! E122  tool "echo": description misses 3/4 quality axes (length 40..600;
          says when to use it; mentions the result)

2026-07-28 readiness  1 item to migrate (a migration diff, not graded)
  ! E104  server declares the logging capability; MCP Logging is deprecated in
          2026-07-28 (SEP-2577) and logging/setLevel is removed
Can a search even single your tools out?
A host can mark tools defer_loading: true, which keeps their definitions out of
the context window until a search returns them; Anthropic recommends turning that
on once tool definitions pass ~10k tokens. Under deferral, a tool nothing
surfaces costs no context and provides no capability, and neither weigh nor
check looks at that.
npx efaimo find "npx -y my-mcp-server"
Two numbers come back, and they are different kinds of claim.
distinct is a property of your catalog: how many tools own a term no other
tool has. A tool that owns none cannot be matched by any query that does not also
match a competitor. That follows from the index, not from a model of how anyone
searches, and it is the number --min-distinct gates on in CI.
distinct  22/24 (91.7%)   tools that own a word no other tool has
probe     24/24 (100%)    returned by a simulated search for their own description

  words  tool                     vocabulary no other tool has
      0  browser_close            none: every word also on browser_click, browser_drag, browser_drop
      0  browser_navigate         none: every word also on browser_tabs, browser_navigate_back, browser_network_requests
      1  browser_evaluate         evaluate
      1  browser_hover            hover
      2  browser_resize           window, resize
(That is @playwright/mcp 0.0.78, a well-maintained server, verbatim. Two of
its twenty-four tools have no word of their own, and two more own only the word
in their own name, which nobody describing a task would type.)
Four public servers measured this way, with the commands that reproduce each
row, are in the findability report. The
weakest was Notion's official server at 16 of 24, where API-get-user and
API-get-users are different tools and nothing in their vocabulary separates
them.
probe is a simulated BM25 search over the four fields tool search matches
on, and it is labelled a simulation because it is one. It reads 100% on both the
official reference server and playwright, so it is a floor test that catches an
empty description or a literal duplicate, not a ranking. find says that on
every run rather than letting a saturated number look like a good score.
There is no findability grade, on purpose: docs/METHODOLOGY.md has the method, its limits, and why.
From an agent
efaimo mcp runs efaimo as a small, read-only MCP server, so an agent can lint or
weigh a skill mid-session, before it commits it to context:
npx efaimo mcp # stdio server exposing efaimo_check_skill and efaimo_weigh_skill
It reads files only (it spawns no process and opens no socket), and the
token-spending test is not exposed. Client config and recipes are in
docs/INTEGRATIONS.md.
How it works
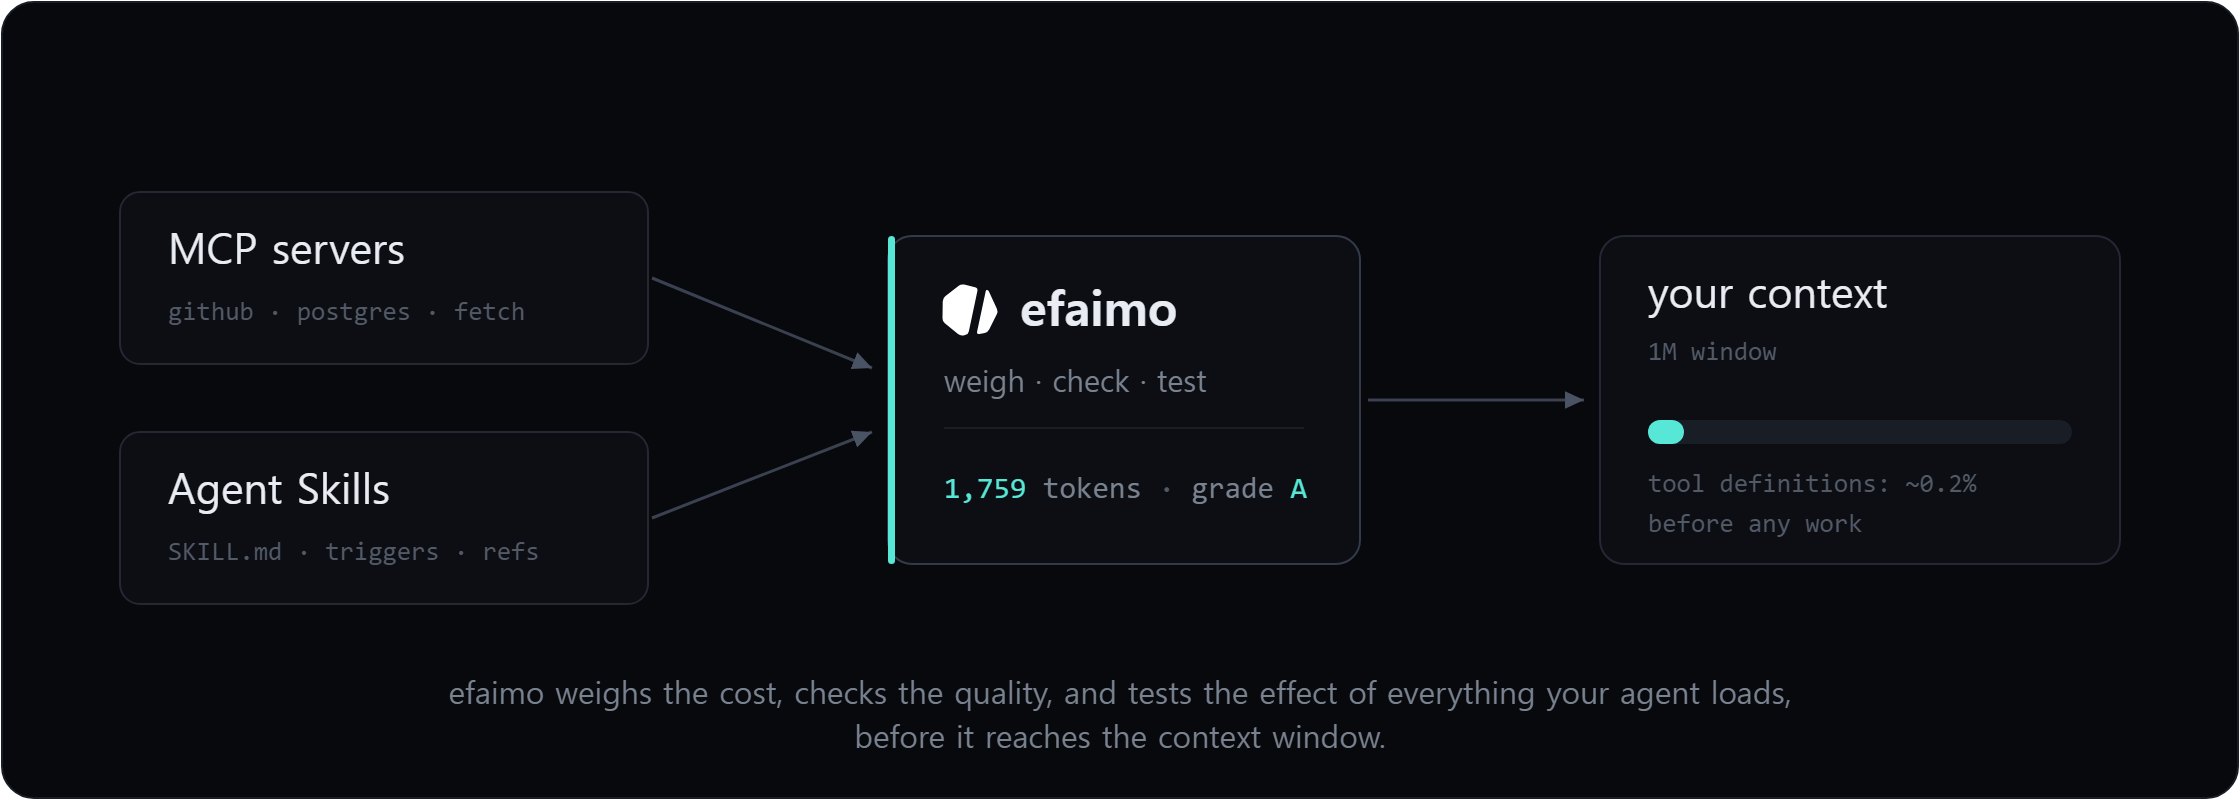
efaimo sits between your agent and everything it loads, measures the cost the way your host actually serializes it, and grades the quality, before any of it reaches your context window.
How it compares
Focused tools already own single slices of this space, and some are very good. efaimo is the one tool that covers the whole audit surface. As of mid-2026:
| efaimo | skill-validator | skillgrade | upskill | mcp-spec-check | conformance (official) | |
|---|---|---|---|---|---|---|
| Agent Skills linting | yes | yes | no | no | no | no |
| Skill token cost | yes (3-level split) | yes | no | no | no | no |
| Skill outcome testing | with/without A/B trials (experimental) | static LLM scoring | yes, and more thoroughly: Docker-isolated runs, script + LLM-rubric graders, weighted scores, CI pass-rate gates | yes (generate + eval, code agents) | no | no |
| MCP tool-definition cost | yes (3 serializations, --anthropic exact) | no | no | no | no | no |
| MCP quality rules | yes | no | no | no | no | no |
| 2026-07-28 readiness | migration diff: what breaks and how to fix | no | no | no | yes/no verdict | official test suite |
| CI budget gate + badge | yes (token budget) | no | pass-rate threshold | no | no | no |
Read that table honestly: on skill outcome testing, skillgrade is the more
serious tool and we would use it over our own efaimo test for anything
depending on the result. Ours is one experimental subcommand in an audit CLI;
theirs is a testing framework. efaimo's claim is the row count, not any single
row.
SkillsBench, whose paper this
README cites, is not in the table because it is a benchmark rather than a tool
you point at your own work: a fixed suite of tasks with packaged environments
and verifiers, extensible by contributing tasks upstream. Useful for the
question "do skills help in general", which is why we cite it, and not for
"does mine help", which is what efaimo test and skillgrade answer.
efaimo runs the official conformance suite for you (check --conformance on
http targets) and complements security scanners such as Snyk agent-scan and the
skills installer (npx skills) rather than replacing them. If your server is
built on the TypeScript SDK, efaimo tells you what breaks and why, and
@modelcontextprotocol/codemod
rewrites the SDK v1 to v2 call sites for you. Diff, codemod, re-check.
"Doesn't tool search already solve this?"
Partly, and that is the point. Anthropic ships a
tool search tool:
mark tools defer_loading: true and the model discovers schemas on demand
instead of carrying all of them, with discovered schemas appended so the prompt
cache survives. Where it applies, it is a better fix than anything a linter can
tell you, and efaimo's own rules point at it (E127 and E128 suggest deferred
loading as a remedy).
It does not make measurement unnecessary, for three reasons. It is opt-in per
tool, so somebody has to decide which tools are worth deferring, and that
decision needs the per-tool numbers. It is a client-side feature, so it says
nothing about what your server publishes to hosts that do not implement it.
And a mitigation you cannot measure is a mitigation you are trusting on faith:
weigh reports the definitions your server actually ships, which is the input
every mitigation operates on.
And there is a fourth reason we did not have when this section was written. Deferring a tool does not remove the question, it replaces
it: a deferred tool that no search returns costs nothing and does nothing, so
the thing worth measuring becomes whether each tool can be picked out of the
catalog at all. efaimo find measures that, and on four public servers it
found two to eight tools apiece that own no word their neighbours lack.
Deferral is what makes findability matter, not what makes it moot.
If deferred loading covers your whole setup, run weigh and find once and
see what it costs you and what it hides; those answers are worth more than our
opinion.
Install
Nothing to install. Use npx:
npx efaimo check --skill ./skills/
Or add it to a project with npm i -D efaimo, or the GitHub Action:
- uses: efaimo-ai/efaimo@v0
  with:
    command: check --skill ./skills --strict
The Action is listed on the GitHub Marketplace.
Gate a pull request on context-window growth, too:
npx efaimo weigh "npx -y my-server" --out base.json          # record a baseline
npx efaimo weigh "npx -y my-server" --diff base.json --allow-increase 10
--badge badge.svg writes an SVG plus a shields.io endpoint JSON for your
README. These two are real efaimo output for the reference server:

More recipes (pre-commit, GitLab, editor audit, programmatic use): docs/INTEGRATIONS.md.
Rules at a glance
| family | covers |
|---|---|
| S101 to S108 | skills: frontmatter and trigger quality, trigger collisions, context budget, reference integrity, injection hygiene, a filename one capitalisation away from SKILL.md, and a reference file nothing points at |
| E101 to E118 | MCP 2026-07-28 readiness: deprecated primitives, statelessness, server/discover, resultType, cache fields, transport |
| E121 to E128, E130 | MCP quality: description quality, annotations, schema hygiene, tool-count and token-cost budgets |
| E141 to E146 | MCP findability: exclusive vocabulary, whether a search returns the tool, indistinguishable pairs, names that carry no domain word |
E000 is not a finding about your server: it means one of efaimo's own rules
threw and was skipped, so the report is incomplete. It is never scored.
Quality (E12x-E13x) and skill (S) findings set the letter grade; readiness
findings (E101-E118) are reported as an ungraded migration diff, which
--strict-readiness can turn into a non-zero exit
without touching the grade. Findability findings (E14x) belong to efaimo find
and never touch a grade either.
Every finding carries a stable id you can suppress or link. See
docs/RULES.md.
Roadmap
- Harden
efaimo test: a length-matched placebo arm (the control currently gets no system prompt at all, which confounds the skill's content with having any system prompt), multi-turn tool-use trials, and judge calibration, so the experimental harness earns unqualified trust. A separately chosen judge model and confidence intervals on the delta are done. - Readiness rules for the two 2026-07-28 changes that have none yet: the
Mcp-Method/Mcp-Namerequest headers (SEP-2243), and Tasks moving out of core into theio.modelcontextprotocol/tasksextension (SEP-2663). - A public, continuously updated Agent Skills Quality Index over a broad corpus.
Stability
efaimo is 0.x. The commands are stable, but the rule set, grades, and exact output may change between minor versions until 1.0; pin a version in CI if you need reproducible thresholds. Every finding keeps a stable id.
Honest scope
efaimo is a linter and cost profiler, not a security scanner. Its injection checks
are info-level heuristics that an attacker evades trivially; a clean report is not a
security pass. For supply-chain safety use a dedicated scanner such as Snyk
agent-scan. Token figures are estimates unless you opt into --anthropic; the
method and its known bias are in docs/METHODOLOGY.md.
About
Built by efaimo ai, open tooling for the space between hosts
and tools. efaimo is the flagship CLI; capabilities grow as subcommands under one
name. Its site is efaimo.com. Apache-2.0. See CONTRIBUTING.md and
docs/RULES.md to add a rule.
EFAIMO AI is a registered trademark of the publisher (KR 40-2585820, class 42).
The lowercase efaimo ai used throughout is the same mark; the package name and
the commands stay lowercase.
efaimonpm install efaimo